Data skew in Apache Spark: how to see it, and nine ways to fix it
One key holding most of the rows turns a parallel job into a serial one. Here is how to measure skew rather than guess at it, nine fixes with the partition distributions and correctness checks for each, and thirty interview questions on identifying and resolving it.
- Architecture: how a shuffle creates skew
- Which kind of skew is it?
- The dataset
- Step 1: measure it
- How do you read the task metrics summary?
- Can you detect skew before running the job?
- Fix 1: broadcast the small side
- Fix 2: let adaptive execution split the partition
- Fix 3: salting
- Fix 4: isolate the hot key
- Fix 5: pre-aggregate before the join
- Fix 6: change the key or the layout
- Fix 7: iterative broadcast join
- Fix 8: a custom partitioner
- Fix 9: drop the rows that should not be there
- What about the skew hint?
- Which skew fix should you choose?
- What does it look like when skew wins?
- Putting it together: one dataset, every fix measured
- Anti-patterns worth measuring
- Production notes
- Key takeaways
- References
- Trademarks
TL;DR
- Skew is not “slow”. It is one task doing most of the work while the rest of the cluster waits, so adding executors changes nothing.
- Measure it before fixing it. The number that matters is the ratio of the largest partition to the median: on the dataset below it is 27x, and salting brings it to 1.9x.
- Adaptive execution can split a skewed partition for you, but only when a partition exceeds 256 MB by default, so on smaller data it never fires however lopsided the key is.
- Broadcasting the small side removes the shuffle entirely, which is the only fix that makes skew irrelevant rather than survivable. Reach for it first.
- Thirty interview questions on this topic are in Spark internals interview questions.
- Every fix here changes the physical layout and must not change the answer. Each one below is checked against the unskewed result, because a salted join with a wrong replication step silently drops or duplicates rows.
A skewed job looks wrong in a specific way. The stage sits at 199 of 200 tasks complete for a long time, one executor’s GC climbs, and nothing you do to the cluster helps. That shape is diagnostic: the work is not too large, it is too unevenly divided, and a single task has become the critical path.
This post uses one deliberately skewed dataset throughout, measures the distribution, and then applies nine fixes, reporting the partition distribution and a correctness check for each. The dataset is small so it runs on a laptop, which means the interesting numbers are structural, row counts and partition ratios, rather than timings. Timings on a laptop would tell you about page cache and JVM warm-up, not about skew.
Architecture: how a shuffle creates skew
Spark parallelises by partition, and a shuffle assigns rows to partitions by hashing the key. If one key holds most of the rows, one partition holds most of the rows, and one task processes them.
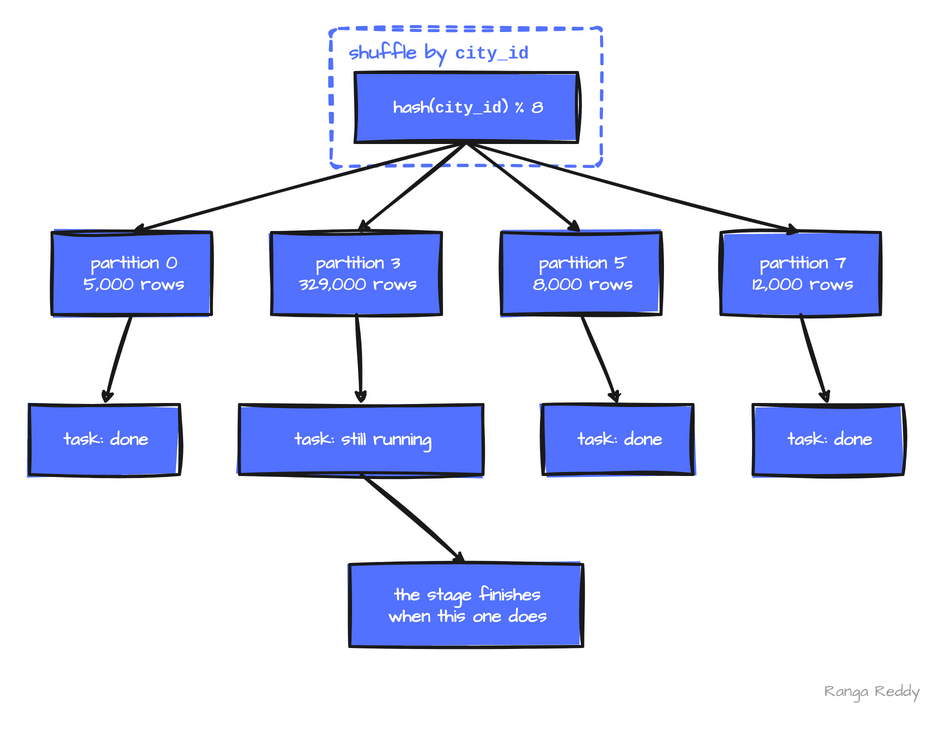 The stage ends when its slowest task ends.
Two consequences follow, and both are counter-intuitive until you see the shape:
- More executors do not help. The stage cannot finish before its longest task, and that task is one thread on one executor.
- More partitions often do not help either.
spark.sql.shuffle.partitionsdivides the key space, not a single key. Raising it from 200 to 2000 splits the small keys further and leaves the hot key exactly where it was.
That second point is why “increase shuffle partitions” is such common and such useless advice for skew. It is the right fix for partitions that are uniformly too big, and the wrong fix for one partition that is too big.
Adding executors cannot fix skew. The stage ends when its slowest task ends, and that task is one thread processing one partition, so extra executors only add parallelism to the tasks that were already finishing early. A job that got no faster after you doubled the cluster is the clearest signal that the critical path is a single partition.
Which kind of skew is it?
“Skew” gets used for three different problems that need different fixes, and naming yours first saves you from applying the wrong one.
| Kind | What is uneven | Typical cause | What fixes it |
|---|---|---|---|
| Key skew | Rows per key | One tenant, one default value, one null substitute | Salting, broadcast, isolating the key |
| Partition skew | Rows per partition, with keys evenly spread | Too few partitions, or a partitioner that collides | More partitions, or a better partition expression |
| Record skew | Bytes per row, with rows evenly spread | One row holds a huge array, blob or JSON document | Splitting the wide column out, or capping it upstream |
The distinction matters because the usual advice contradicts itself across
them. Raising spark.sql.shuffle.partitions is the correct fix for partition
skew and a useless one for key skew, as the numbers later in this post show.
Record skew is the one people miss entirely: every partition holds the same
number of rows, the row counts look perfect, and one task still runs for an
hour because its rows are a thousand times larger. If your partition counts are
balanced and one task is still slow, measure bytes rather than rows.
This post is about key skew, which is the most common and the one with the most fixes.
The dataset
One city holds 80% of the trips, which is the shape of most real skew: a default value, a null-substitute, a single huge tenant, or one popular product.
from pyspark.sql import SparkSession, functions as F

spark = (SparkSession.builder.appName("skew").master("local[4]")
         .config("spark.sql.shuffle.partitions", "8")
         .config("spark.sql.adaptive.enabled", "false")   # off, to see the raw problem
         .getOrCreate())

trips = (spark.range(0, 400000)
    .select(F.col("id").alias("trip_id"),
            F.when(F.col("id") % 100 < 80, F.lit(7))          # 80% land on city 7
             .otherwise(F.col("id") % 400).alias("city_id"),
            (F.col("id") % 4000 / 100.0).cast("double").alias("fare")))
trips.write.mode("overwrite").parquet("/tmp/skew/trips")

cities = spark.range(0, 400).selectExpr("id AS city_id", "concat('city-', id) AS city_name")
cities.write.mode("overwrite").parquet("/tmp/skew/cities")

t = spark.read.parquet("/tmp/skew/trips")
c = spark.read.parquet("/tmp/skew/cities")
Step 1: measure it
Two measurements are worth taking, and they answer different questions.
The key distribution tells you whether you have skew and which key is hot:
total = t.count()
top = t.groupBy("city_id").count().orderBy(F.desc("count")).limit(5).collect()
for r in top:
    print(f"city_id={r[0]:<5} rows={r[1]:<8} {100.0 * r[1] / total:5.1f}% of {total}")
city_id=7     rows=320000    80.0% of 400000
city_id=80    rows=1000       0.2% of 400000
city_id=82    rows=1000       0.2% of 400000
city_id=180   rows=1000       0.2% of 400000
city_id=96    rows=1000       0.2% of 400000
Every city other than 7 holds exactly 1,000 rows here, so which four appear after the first is an arbitrary tie-break and will differ on your run. The first line is the finding: one key out of 81 holds four fifths of the table.
The partition distribution tells you how bad it will be after the shuffle, which is the number that predicts the stall:
def partition_stats(df, label):
    rows = (df.withColumn("pid", F.spark_partition_id())
              .groupBy("pid").count().orderBy("pid").collect())
    counts = [r[1] for r in rows]
    median = sorted(counts)[len(counts) // 2]
    print(f"{label:<34} partitions={len(counts)} max={max(counts)} "
          f"median={median} ratio={max(counts) / median:.1f}")
    return counts

partition_stats(t.repartition(8, "city_id"), "repartitioned by city_id")
repartitioned by city_id partitions=8 max=329000 median=12000 ratio=27.4
A ratio near 1 is healthy; this is 27. That single number is the one to track, because it is what changes when a fix works. It also survives being run on a sample, so you can measure it on a slice of production data without a full job.
In the Spark UI the same thing appears in the stage’s task table: sort by duration or by shuffle read size and look at max against the 75th percentile. The summary metrics row gives you min, 25th, median, 75th and max directly, and a max an order of magnitude above the median is the signature.
How do you read the task metrics summary?
The partition counts above are a pre-flight check. Once a job has run, the evidence is in the stage’s summary metrics, and you do not have to squint at the UI to get them. Spark exposes the same numbers over REST while the application is alive:
curl -s "http://localhost:4040/api/v1/applications/$APP/stages/$STAGE/0/taskSummary?quantiles=0,0.25,0.5,0.75,1.0"
For the skewed join above, the shuffle-read stage reports this:
  metric                          min       25th     median       75th        max
  duration (ms)                    29         38        194        217        277
  peak exec mem (MiB)               9          9          9          9         28
  shuffle read records          5,047      9,054     12,046     14,050    329,055
  shuffle read (KiB)                2          2          3          4         50
  shuffle write records             5          9         11         12         14
Read the row, not the column. A healthy metric rises gently from min to max.
shuffle read records goes 5,047 → 9,054 → 12,046 → 14,050 and then jumps to
329,055: four of the five quantiles agree with each other and the fifth is
twenty-seven times the median. That discontinuity between the 75th percentile
and the max is the signature, and it is the same 27x the partition ratio
predicted before the job ran.
Two things in that table are worth more attention than they usually get.
Duration is the weakest signal here. Max over median is 277 / 194, only 1.4x, on data that is genuinely 27x lopsided. On a small local dataset, JVM warm-up and scheduling dominate the per-task time, so duration understates the problem badly. Shuffle read records is the honest column. At production scale duration does separate, but it separates later and less reliably than the row counts do, so lead with the counts.
Peak execution memory moves before anything fails. 9 MiB across the first four quantiles and 28 MiB at the max. That is the task that will hit the executor’s memory limit first, and watching this column is how you see an out-of-memory failure coming rather than reading about it in a stack trace.
Spill is the other column to watch, and it is zero here only because the
dataset is small. A max row with non-zero diskBytesSpilled while the median is
zero means one task ran out of execution memory and started writing to disk,
which is skew turning into I/O.
Can you detect skew before running the job?
Yes, and it costs one aggregation. This reports everything worth knowing about a key before you join or group on it:
from pyspark.sql import functions as F

def skew_report(df, key, label=""):
    counts = df.groupBy(key).count()
    s = counts.agg(
        F.count("*").alias("keys"),
        F.sum("count").alias("rows"),
        F.max("count").alias("max_rows"),
        F.expr("percentile_approx(count, 0.5)").alias("median_rows"),
        F.skewness("count").alias("skewness"),
        F.kurtosis("count").alias("kurtosis"),
    ).collect()[0]
    top = counts.orderBy(F.desc("count")).limit(1).collect()[0]
    print(f"[{label}] keys={s['keys']} rows={s['rows']} "
          f"hottest={top[key]} share={100.0 * top['count'] / s['rows']:.1f}% "
          f"max/median={s['max_rows'] / s['median_rows']:.1f}")
    return s

skew_report(t, "city_id", "trips")
# [trips] keys=81 rows=400000 hottest=7 share=80.0% max/median=320.0
Two numbers there are worth acting on. Top-key share answers “is there a hot key”, and max over median answers “how bad will the shuffle be”. Both are cheap, both are interpretable, and both move in the right direction when a fix works.
Kurtosis is the wrong tool, and it is worth seeing why
Statistical moments get recommended for this and they do not behave. Running the same report across four distributions:
| Distribution | Top-key share | max/median | skewness | kurtosis |
|---|---|---|---|---|
| 80% on one key | 80.0% | 320.0 | 8.83 | 76.01 |
| 20% on one key | 20.0% | 80.0 | 17.83 | 316.00 |
| Mildly uneven, no hot key | 0.3% | 1.0 | -19.22 | 374.82 |
| Perfectly uniform | 0.2% | 1.0 | undefined | undefined |
The worst case scores the lowest kurtosis of the three. The 80% distribution is by far the most damaging to a shuffle and reports 76, while a distribution with no hot key at all reports 375. Kurtosis measures tail weight relative to the spread of the whole distribution, and a table with 81 keys where one is enormous has a different shape from one with 401 keys where one is slightly small, in a way that has nothing to do with how Spark will partition it.
Note the last row too: when every key holds exactly the same number of rows the standard deviation is zero, and both moments come back null rather than zero. Code that formats them without a null check fails on the one input that should have been easiest.
Top-key share and max over median ranked all four correctly. Use those.
Fix 1: broadcast the small side
If one side fits in memory, broadcast it. There is then no shuffle of the large side, so there is no partition for the hot key to overfill and the skew stops mattering at all.
b = t.join(F.broadcast(c), "city_id")
ep = b._jdf.queryExecution().executedPlan().toString()
strategy = BroadcastHashJoin [city_id#1L], [city_id#3L], Inner, BuildRight
Exchange nodes in plan = 1
join rows = 400000
The one Exchange is the broadcast being built from the 400-row dimension, not a
shuffle of the 400,000-row fact. Nothing about the key distribution matters any
more.
This is the first thing to try and the most commonly missed, because the threshold is 10 MB and dimensions are often just over it as stored while being well under it after a filter and a projection. Reduce the small side first, then look at whether it broadcasts.
When it does not apply: both sides large, or a join type that forbids broadcasting that side. A full outer join can never be a broadcast hash join, and for a right outer only the left may be broadcast. Those rules are the subject of Apache Spark joins in depth.
Fix 2: let adaptive execution split the partition
Adaptive query execution can detect an oversized partition after the shuffle has run and split it into several, joining each piece against a copy of the matching rows from the other side. It is on by default.
spark.conf.set("spark.sql.adaptive.enabled", "true")
spark.conf.set("spark.sql.adaptive.skewJoin.enabled", "true")
j = t.join(c, "city_id").groupBy("city_name").agg(F.sum("fare").alias("s"))
qe = j._jdf.queryExecution()
j.collect()                       # execute this plan, then read it back
print(qe.executedPlan().toString())
# skewJoin.enabled = true
*(5) SortMergeJoin(skew=true) [city_id#1L], [city_id#6L], Inner
  +- AQEShuffleRead coalesced and skewed

# skewJoin.enabled = false
*(5) SortMergeJoin [city_id#1L], [city_id#6L], Inner
  +- AQEShuffleRead coalesced
(skew=true) on the join operator and and skewed on the shuffle read are the
two markers that it fired.
The catch, and it is a big one. The rule computes one threshold as the larger of two numbers:
  def getSkewThreshold(medianSize: Long): Long = {
    conf.getConf(SQLConf.SKEW_JOIN_SKEWED_PARTITION_THRESHOLD).max(
      (medianSize * conf.getConf(SQLConf.SKEW_JOIN_SKEWED_PARTITION_FACTOR)).toLong)
  }
so a partition must exceed both skewJoin.skewedPartitionFactor times the median
(default 5.0) and skewJoin.skewedPartitionThresholdInBytes (default 256MB).
Taking the maximum is what makes the byte floor absolute: on a dataset where no
partition reaches 256 MB the rule can never fire, however lopsided the
distribution is. The example above only fires because I lowered that floor to
1MB.
So AQE skew handling is real and it is not a general answer. It helps on genuinely large partitions and does nothing on a 27x ratio between partitions of 300 MB and 12 MB. Check the markers rather than assuming.
Fix 3: salting
Salting is the general fix and the one to understand properly, because a half-implemented version silently changes results.
The idea: add a random bucket number to the key on the large side so the hot key becomes N keys, and replicate the small side once per bucket so every piece still finds its match.
flowchart TB
  subgraph L["large side"]
    A["city_id=7"] --> A1["(7, salt=0)"]
    A --> A2["(7, salt=1)"]
    A --> A3["(7, salt=...)"]
    A --> A4["(7, salt=7)"]
  end
  subgraph R["small side, replicated"]
    B["city_id=7"] --> B1["(7, 0)"]
    B --> B2["(7, 1)"]
    B --> B3["(7, ...)"]
    B --> B4["(7, 7)"]
  end
  A1 --> J["join on (city_id, salt)"]
  B1 --> J
  A4 --> J
  B4 --> J
  J --> O["same rows as the plain join,<br/>spread over 8 partitions"]
SALT = 8

# large side: one random bucket per row
tf = t.withColumn("salt", (F.rand(seed=7) * SALT).cast("int"))

# small side: one copy per bucket, so no match is lost
cf = c.withColumn("salt", F.explode(F.array([F.lit(i) for i in range(SALT)])))

salted = tf.join(cf, ["city_id", "salt"])
small side rows: 400 -> 3200 after explode by 8
fact repartitioned by (key, salt)   partitions=8 max=92841 median=50039 ratio=1.9
join rows = 400000   same as plain join: True
The ratio drops from 27.4 to 1.9, and the row count is unchanged. That second
half is not a formality. The replication step is where salting goes wrong: forget
the explode and rows of the hot key whose salt has no match disappear, and
replicate the wrong side and you get duplicates. Always compare the row count,
and ideally the full result, against the unsalted join.
Three practical notes:
- The cost is the replication. The small side grows by a factor of
SALT, so salting is cheap when it is small and pointless when it is not. - Salt only the hot keys if you can. Applying the salt conditionally,
when(col("city_id") == 7, rand * SALT).otherwise(0), keeps the replication to one key and needs the dimension exploded only for that key. - Pick
SALTfrom the ratio, not from taste. A 27x imbalance needs roughly 27 buckets to level; 8 got it to 1.9 here because the other partitions grew too.
Fix 4: isolate the hot key
When one key is hot and you know which, split the query: broadcast-join the hot key on its own, shuffle-join everything else, and union the two.
HOT = 7
hot = (t.filter(F.col("city_id") == HOT)
        .join(F.broadcast(c.filter(F.col("city_id") == HOT)), "city_id"))
cold = (t.filter(F.col("city_id") != HOT)
         .join(c.filter(F.col("city_id") != HOT), "city_id"))
result = hot.unionByName(cold)
hot rows=320000 cold rows=80000 total=400000
matches plain join: True
The hot side is a broadcast join, so it never shuffles. The cold side is a normal shuffle join over a now-uniform key distribution. It is more code than salting and it is easier to reason about, since nothing is replicated and nothing is random. It needs you to know the hot key, which the measurement step gives you.
Fix 5: pre-aggregate before the join
If the query aggregates after joining, do the aggregation first. Skew in an aggregation is far cheaper than skew in a join, because the hot key collapses to one row rather than producing a large intermediate.
# 400,000 rows into the join
join_then_agg = (t.join(F.broadcast(c), "city_id")
                  .groupBy("city_name").agg(F.sum("fare").alias("s")))

# 81 rows into the join
agg_then_join = (t.groupBy("city_id").agg(F.sum("fare").alias("s"))
                  .join(F.broadcast(c), "city_id"))
rows into the join: pre-aggregated=81 vs raw=400000
same answer: True
This is the largest structural win available when it applies, because it changes
the size of the problem rather than its distribution. It applies only when the
aggregate does not need columns from the dimension in its grouping, which is why
the version above groups by city_id and joins for the name afterwards.
Two phases, not one
The same idea works when there is no join at all and the aggregation itself is skewed. Instead of shuffling every row to its key’s partition, aggregate on a salted key first and then combine the partials:
SALT = 16
salted = (t.withColumn("salt", (F.rand(7) * SALT).cast("int"))
            .groupBy("city_id", "salt").agg(F.sum("fare").alias("partial")))
result = salted.groupBy("city_id").agg(F.sum("partial").alias("s"))
[one-phase, shuffle by key ] partitions=8 max=329000 median=12000 ratio=27.4
[two-phase, salted partials] partitions=8 max=180    median=163   ratio=1.1
partial rows entering the final aggregate: 1296
same answer as one-phase: True (81 keys)
The first shuffle is balanced because the salt spreads the hot key, and the
second shuffle is trivial because only 1,296 partial rows survive it, against
the 400,000 the one-phase version moves. This works for sum, count, min
and max, which combine associatively. It does not work directly for
avg, count(distinct) or a median: carry sum and count separately and
divide at the end, or the partials will not compose.
The RDD version of the same lesson
If you are still using the RDD API, this distinction has a name. groupByKey
ships every value across the network; reduceByKey combines on the map side
first. Same inputs, same answer, measured shuffle write:
| Operation | Shuffle write | Answer |
|---|---|---|
pairs.groupByKey().mapValues(sum) |
1,272,588 bytes | 81 keys |
pairs.reduceByKey(lambda a, b: a + b) |
5,184 bytes | 81 keys |
245 times less data moved for an identical result, and the gap widens with
the size of the hot key, because every one of its values is what groupByKey
is shipping. The DataFrame API applies the same partial aggregation for you,
which is one of the better reasons to prefer it.
Fix 6: change the key or the layout
Two slower fixes, for skew you have to live with.
Bucketing. Writing both tables bucketed on the join key with the same bucket count removes the shuffle from every future join on that key:
trips.write.mode("overwrite").bucketBy(8, "city_id").sortBy("city_id").saveAsTable("trips_b")
cities.write.mode("overwrite").bucketBy(8, "city_id").sortBy("city_id").saveAsTable("cities_b")
With broadcast disabled so the join has to shuffle, the difference is the whole point:
[unbucketed join] Exchange=2  SortMergeJoin=True
[bucketed join  ] Exchange=0  SortMergeJoin=True
Zero exchanges. The plan reads straight from the files into the sort and the join, because both sides are already partitioned the same way:
*(3) SortMergeJoin [city_id#8L], [city_id#10L], Inner
 :- *(1) Sort [city_id#8L ASC NULLS FIRST], false, 0
 :  +- *(1) Filter isnotnull(city_id#8L)
 :     +- FileScan parquet spark_catalog.default.trips_b2[city_id#8L,fare#9]
It does not fix the skew. Reading the bucketed table back:
per-bucket rows: [343000, 26750, 21250, 9000]
max=343000 median=26750 ratio=12.8
The hot key still lands in one bucket, so one task still does most of the work. Bucketing moves the cost from “shuffle on every query” to “one slow task on every query”, which is a real win on a table joined repeatedly and no help at all with the imbalance. Pair it with salting rather than treating it as a replacement, and note the operational cost: the bucket count is fixed at write time, both sides must agree on it, and changing it means rewriting the table.
Table-format layout. Iceberg and Hudi give you more control over file layout, through partitioning, sorting and clustering on write. That helps two things: pruning, so a filtered query reads fewer files, and file sizing, so a scan is not dominated by one enormous file. Neither redistributes a hot join key, because the key’s rows still have to meet in one place during the shuffle. Treat layout as the fix for scan-side problems and salting or AQE as the fix for shuffle-side ones.
A composite key. If the hot key is hot because it is a placeholder, a
-1, an UNKNOWN, or a null substitute, the real fix is upstream. Those rows
often should not be joined at all. Filtering them out before the join, or
replacing the placeholder with something genuinely distinct, is a data-modelling
change that makes the skew disappear rather than spreading it.
Fix 7: iterative broadcast join
Broadcast is the best answer to skew and it has one limit: the small side has to fit in the driver and in every executor. When it is too large for that but still much smaller than the skewed side, you can broadcast it in pieces.
The idea is to split the small side into chunks, broadcast-join each chunk against the full large side, and union the results. Each iteration is a broadcast join, so no iteration shuffles the skewed side.
CHUNKS = 4
total = 0
for i in range(CHUNKS):
    part = c.filter((F.col("city_id") % CHUNKS) == i)
    j = t.join(F.broadcast(part), "city_id")
    total += j.count()
chunks=4 total rows=400000 matches plain: True
every chunk a BroadcastHashJoin: True
Correctness holds because the chunks partition the small side by key: every key appears in exactly one chunk, so every matching pair is produced exactly once. If the chunks overlapped, rows would be duplicated, which is the one way to get this wrong.
What it costs. The large side is read once per chunk. Four chunks means four scans of the skewed table, so this trades repeated reads for the elimination of a shuffle. That is worth it when the shuffle is the bottleneck and the scan is cheap — a partitioned or pruned source — and a bad trade when the large side is expensive to read and the shuffle would have been tolerable.
Use it when the small side is a few hundred megabytes: too big for one broadcast, far too small to justify shuffling a skewed table against it.
Fix 8: a custom partitioner
Everything so far changes the data. A custom partitioner changes the function
that maps keys to partitions instead, which is the most direct expression of the
problem: HashPartitioner sends every row with the same key to one partition,
and that is the whole of the skew.
This is an RDD-level tool. The DataFrame API does not expose the partitioner, so
this applies to RDD pipelines or to a deliberate detour through .rdd.
N = 8
pair = t.rdd.map(lambda r: (r["city_id"], r["trip_id"]))

def spread(k):
    # the known hot key goes anywhere; everything else hashes normally
    return random.randrange(N) if k == 7 else hash(k) % N

balanced = pair.partitionBy(N, spread)
The distributions, over the same 400,000 rows:
HashPartitioner            max=330000  min=10000   ratio=33.0
custom partitioner         max=50699   min=49506   ratio=1.0
A 33× imbalance becomes 1.0×. That is the same outcome salting achieves, reached by a different route: salting rewrites the key so the default partitioner spreads it, while a custom partitioner leaves the key alone and replaces the partitioner.
The catch is the same one salting has. Once the hot key is spread across
partitions, rows with that key are no longer co-located, so any operation that
requires them together — a join on that key, a reduceByKey — has to be
completed in a second pass. Spreading a key and then joining on it produces wrong
answers, not slow ones. Use this for the aggregate-then-combine shape, where the
partial results are merged afterwards.
It is also the fix with the most operational cost: a partitioner is code, it hard-codes knowledge of which key is hot, and it goes stale when the data changes.
Fix 9: drop the rows that should not be there
The cheapest fix is the one that removes the work. A hot key is very often a
placeholder — -1, UNKNOWN, an empty string, a null substitute — and those
rows frequently have no business being in the join at all.
kept = t.filter(F.col("city_id") != 7)
all trips        = 400000
excluding city 7 = 80000
partitions after join      max=20000   min=20000
Removing one key took the input from 400,000 rows to 80,000 and left a perfectly even distribution. No salting, no replication, no second pass.
This is only a fix if those rows genuinely do not belong, which is a question about the data rather than about Spark. Two cases where it applies cleanly: the placeholder is a sentinel that never matches anything in the dimension table, so the join drops the rows anyway and you are paying to shuffle rows that produce no output; or the rows are filtered out later in the pipeline, and the filter can be moved before the join instead.
Where the hot key is real data with real matches, this is not available and you are back to salting, isolation or a broadcast.
What about the skew hint?
Advice lists frequently include a skew hint, written like this:
SELECT /*+ SKEW('t', 'city_id') */ t.trip_id, c.city_name
FROM t JOIN c ON t.city_id = c.city_id
Apache Spark does not have one. The join strategy hints it recognises are
BROADCAST (with aliases), MERGE, SHUFFLE_HASH and SHUFFLE_REPLICATE_NL.
There is no SKEW among them; the hint is a Databricks extension, and writing it
in Apache Spark does not fail loudly.
Running the query above changed nothing in the plan, produced no skew-handling operator, and returned the same 400,000 rows. The only trace it left was a single line in the driver log:
WARN HintErrorLogger: Unrecognized hint: SKEW(t, city_id)
The contrast is worth seeing: a BROADCAST hint on the same query was honoured
and produced a BroadcastHashJoin. So hints are not being ignored in general —
this one simply does not exist.
A hint that does nothing is worse than no hint, because it looks like the problem has been addressed. If you have inherited a query with a skew hint in it and the skew persists, this is why. The open-source equivalent is AQE’s skew join handling from Fix 2, which needs no hint and is on by default.
Which skew fix should you choose?
| Situation | Fix | Why |
|---|---|---|
| Small side fits in memory after filtering | Broadcast | No shuffle, so skew is irrelevant |
| Query aggregates after the join | Pre-aggregate | Shrinks the input rather than spreading it |
| One or two known hot keys | Isolate them | No replication, no randomness, easy to verify |
| Many hot keys, or unknown ones | Salting | The general answer, at the cost of replicating the small side |
| Partitions genuinely over 256 MB | AQE skew join | Automatic, no query change |
| The same large join runs repeatedly | Bucketing, plus one of the above | Removes the shuffle permanently |
| The hot key is a placeholder | Drop the rows | Removes the work instead of spreading it |
| Small side too big to broadcast, still far smaller | Iterative broadcast | Trades repeated scans for no shuffle |
| RDD pipeline, aggregate-then-combine | Custom partitioner | Replaces the partitioner rather than the key |
You found a SKEW hint in the query |
Nothing; it does not exist | Apache Spark ignores it with a warning |
The order in that table is roughly the order to try things in. Broadcast and pre-aggregation change the shape of the work; salting and isolation only redistribute it; AQE only helps above its threshold.
What does it look like when skew wins?
Skew rarely announces itself as skew. The symptoms, in the order they usually appear:
- A stage stuck at “199/200 tasks complete”, sometimes for longer than the rest of the job took.
- In the stage’s summary metrics, a max shuffle-read size an order of magnitude above the 75th percentile.
ExecutorLostFailureor a container killed by the resource manager, because the one big task exhausted its memory.- Repeated spill on one task only, visible as a large “Spill (disk)” for the max task and nothing for the median.
- A job that got slower after you added executors, since the extra parallelism went to tasks that were already fast.
The last one is the clearest tell. If doubling the cluster changed nothing, the critical path is a single task, and no amount of hardware divides one partition.
Putting it together: one dataset, every fix measured
Every number in this post came from the same 400,000-row table, so they can be read side by side. This is a laptop reproduction rather than a production incident, which means the ratios are the finding and the wall-clock times are not worth quoting.
| Approach | Partition ratio | What it cost |
|---|---|---|
| Do nothing | 27.4 | One task holds 329,000 of 400,000 rows |
| Raise partitions to 2,000 | 320.0 | Worse, plus 1,921 empty partitions |
| Broadcast the small side | n/a | Shuffle removed entirely; needs a side that fits |
| Salt, factor 16 | 2.2 | Dimension replicated 16x |
| Salt, factor 256 | 1.0 | Dimension replicated 256x, rarely worth it |
| Two-phase aggregation | 1.1 | 1,296 partial rows instead of 400,000 |
| Bucketing | 12.8 | Shuffle removed, imbalance untouched |
Read down the middle column and the shape of the advice appears. Broadcast first, because removing the shuffle beats balancing it. If the small side does not fit, aggregate before joining when the query allows it, since collapsing the hot key to one row changes the size of the problem rather than its distribution. If you still need the join at full width, salt with the smallest factor that works, which was 16 here and is rarely 256. And if the same join runs many times a day, bucket it to remove the shuffle permanently, knowing the slow task remains.
The one row worth memorising is the second. It is the most common first attempt and the only one that made things worse.
Anti-patterns worth measuring
Three fixes get applied reflexively. Two of them make the problem worse, and the numbers are more persuasive than the argument.
Raising the partition count
The most common response to a slow shuffle, and for key skew it moves the metric backwards. Repartitioning the same skewed table by the same key:
n=8     non_empty=8   max=329000  median=12000  ratio=27.4
n=64    non_empty=47  max=323000  median=2000   ratio=161.5
n=512   non_empty=74  max=320000  median=1000   ratio=320.0
n=2000  non_empty=79  max=320000  median=1000   ratio=320.0
The max barely moves and the median collapses, so the ratio grows twelvefold.
The hot key hashes to exactly one partition no matter how many there are; all
the extra partitions do is split the keys that were never the problem. At
n=2000 only 79 partitions hold anything at all, so the other 1,921 are pure
scheduler overhead: task launches, empty shuffle blocks, and a longer driver
loop, in exchange for a distribution that is now 320 times lopsided instead of
27.
Raising the partition count is the right fix for partition skew, where the keys are spread evenly and there are simply too few buckets. It has never been a fix for one hot key.
Over-salting
Salting works, and more salt is not better. Holding the same join and varying only the salt factor:
factor=1    ratio= 29.9  dim_rows=400     correct=True
factor=4    ratio= 15.1  dim_rows=1600    correct=True
factor=16   ratio=  2.2  dim_rows=6400    correct=True
factor=64   ratio=  1.2  dim_rows=25600   correct=True
factor=256  ratio=  1.0  dim_rows=102400  correct=True
Balance improves all the way down to 1.0, which is why the temptation exists. Look at the other column. The dimension table is replicated once per salt value, so going from 16 to 256 buys a ratio improvement of 2.2 to 1.0 and costs a 16-fold increase in the side being replicated. Here that is 102,400 rows, which is harmless. On a dimension table of ten million rows it is 2.5 billion, and you have converted a skewed join into an enormous one.
The shape of the curve is the lesson: most of the benefit arrives by about 16, and everything after that is paying linearly for a rounding error. Pick the smallest factor that brings the ratio near 1, measure it, and stop.
Trusting adaptive execution without checking
The third one is quieter. Adaptive execution’s skew handling is on by default
and genuinely good, and it has a threshold: a partition must exceed both
spark.sql.adaptive.skewJoin.skewedPartitionFactor times the median and
spark.sql.adaptive.skewJoin.skewedPartitionThresholdInBytes, 256 MB by
default. Below that it does nothing, silently, however lopsided the key is.
That is the right behaviour, and it means “AQE is on” is not an answer to
“is this stage skewed”. Check AQEShuffleRead in the final plan for a
skew=true marker before assuming anything was split.
Production notes
- Measure before and after with the max-to-median partition ratio. It is one number, it is cheap to compute on a sample, and it is what tells you a fix worked.
- Check the row count after any salting change. The replication step is easy to get subtly wrong, and the failure is silent: wrong results rather than an error.
- Do not reach for
spark.sql.shuffle.partitionsfor skew. It divides the key space, not a single key. It is the right knob for uniformly oversized partitions. - Do not assume AQE has it covered. Confirm
(skew=true)in the final plan. The 256 MB default threshold means it often has not. - Salt only the hot keys where you can, so the small side is replicated for one key rather than all of them.
- Look upstream when the hot key is a placeholder. A
NULL-substitute key that joins to nothing useful is a modelling bug wearing a performance costume. - Re-measure after data growth. Skew is a property of the data, not the query, so a job that was balanced last quarter can stall on the same code.
Key takeaways
Skew is the one performance problem where the usual instincts are actively misleading. It does not respond to more executors, it does not respond to more shuffle partitions, and it does not look like a data problem until you measure the distribution.
The useful reframing is that every fix here does one of three things. It removes the shuffle, which is broadcasting. It shrinks what goes into the shuffle, which is pre-aggregation and filtering. Or it redistributes what the shuffle produces, which is salting, hot-key isolation and AQE’s skew split. The first two change the problem; the third divides it. Try them in that order, because a problem removed needs no tuning.
And whichever you pick, check the answer. Of the nine fixes above, three replicate or split data, and all three can change results if the replication is wrong. The row-count comparison that took one line in every example here is the cheapest insurance in this entire area.
References
- SQL performance tuning for the adaptive-execution and skew-join configuration defaults
- Spark configuration reference for
spark.task.maxFailuresand the retry behaviour a skewed task runs into - Apache Spark joins in depth for the strategy and build-side rules that decide whether broadcasting is even available
- Inside Spark’s Catalyst optimizer for where adaptive execution sits relative to the logical rewrites
Trademarks
Apache Spark, Apache Hudi, Apache Iceberg, Apache Parquet and Apache are either registered trademarks or trademarks of The Apache Software Foundation in the United States and other countries.
Found this useful?
These posts and tools are free. If one saved you an afternoon, you can buy me a coffee.
Comments
Questions, corrections and reviews are welcome. Sign in with GitHub to post; comments are stored in this site's public GitHub Discussions.